The trick: Scope Swap
A map says 90% of US work hours sit on tasks AI benchmarks barely test.
That is a fact about the tests, from a list of 29 benchmarks, not a fact about what AI can do.
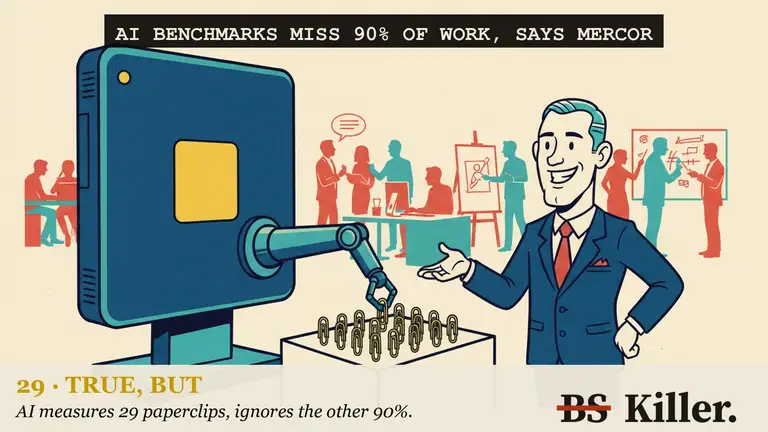
90% of US working hours go to tasks AI benchmarks cover poorly.
Before you read on. Your call?
TRUE, BUT
29
Mercor built it from 29 benchmarks, excluded ones frontier models have saturated, and had an LLM judge tag prompts to O*NET tasks. It says an incomplete list biases coverage down. Only 208 of 923 occupations have a task in at least 5 prompts. RuntimeWire notes the estimate is provisional and depends on Mercor's selection rules.
There’s more to this story.
Membership opens the full investigation, the strongest counterargument and what to do with what you’ve learned.
30 days free, then A$89 a year. Payment card required. Cancel before the trial ends to avoid the first charge.
Review my 30-day free trial →- At sign-up: 30 days free. Payment card required. One introductory trial per customer.
- Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
- You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing hello@bskiller.com. This voluntary refund does not limit your rights under the Australian Consumer Law.
By starting your trial, you agree to the Terms.
BS Killer is published by Inferno Tech Pty Ltd, ABN 27 647 413 474.
Get tomorrow’s check free by email.
Couldn't check your access. That's on us.
The trick has a name
We call it Scope Swap: applies to far less than it sounds like. You'll see it again. Learn to spot it →
Receipts
- Supports mercor.com:
90% of American working hours are spent on tasks with little or no coverage from existing benchmarks
- Context mercor.com:
we start with a list of 29 benchmarks selected for their quality and economic relevance
- Context mercor.com:
we then ask an LLM judge to tag each benchmark prompt with as many O*NET tasks as it thinks correspond to that prompt
- Context mercor.com:
only 208 of 923 occupations have a task with at least 5 benchmark prompts
- Context mercor.com:
Benchmarks are not yet saturated by frontier models.
- Refutes mercor.com:
Any incomplete list will necessarily bias down estimates of economic coverage
- Context mercor.com:
We validate our LLM tagging with human expert tags on Mercor’s APEX benchmarks, a subset of this list of 29.
- Context runtimewire.com:
Mercor says the coverage estimate is provisional and depends on its selection rules.
- Context the-decoder.com:
a field dominated by programming that makes up just 7.6 percent of total US employment
Open the Receipts Pack → What each source proves, every figure traced, and what would change our verdict.