The trick: Scope Swap
Claude Opus 5.5 can now rebuild real programs from scratch, says the viral post.
The 18.5% is real. It means 37 of 200 programs cloned by running the original and passing a finite test suite.
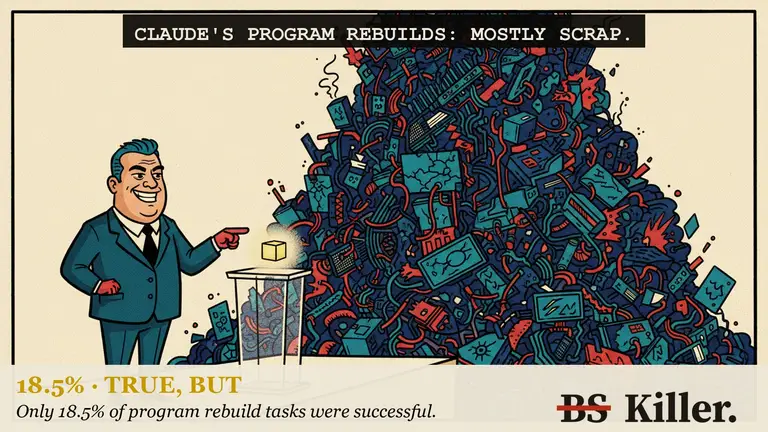
Opus 5.5 can rebuild real programs from scratch, scoring 18.5% on ProgramBench after 0% in May.
Before you read on. Your call?
TRUE, BUT
37 of 200
Vals AI and the benchmark's own leaderboard both report 18.5%, and the May paper found no model fully resolved any task.
The twist
The model gets the original program to run and probe, 163 of 200 tasks still fail at least one test, and the authors warn their tests can never cover all inputs.
There’s more to this story.
Membership opens the full investigation, the strongest counterargument and what to do with what you’ve learned.
30 days free, then A$89 a year. Payment card required. Cancel before the trial ends to avoid the first charge.
Review my 30-day free trial →- At sign-up: 30 days free. Payment card required. One introductory trial per customer.
- Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
- You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing hello@bskiller.com. This voluntary refund does not limit your rights under the Australian Consumer Law.
By starting your trial, you agree to the Terms.
Inferno Tech Pty Ltd t/a BS Killer, ABN 27 647 413 474
Get tomorrow’s check free by email.
Couldn't check your access. That's on us.
The trick has a name
We call it Scope Swap: applies to far less than it sounds like. You'll see it again. Learn to spot it →
Receipts
- Supports vals.ai:
Claude Opus 5.5 ranks first on ProgramBench with 18.50%
- Supports programbench.com:
Given only a compiled binary and its documentation, agents must architect and implement a complete codebase that reproduces the original program's behavior.
- Supports arxiv.org:
We evaluate 9 LMs and find that none fully resolve any task
- Context vals.ai:
a task is counted as Fully Resolved only when the submitted implementation passes all tests.
- Context vals.ai:
Claude Opus 5.5 87.0% 130 37
- Context programbench.com:
The agent can run the given program with any input and observe exactly what it does
- Refutes programbench.com:
Note that behavioral tests can never cover all possible inputs.
- Context programbench.com:
ranging from small terminal utilities like jq and ripgrep to massive software projects like the PHP compiler
- Refutes arxiv.org:
Models favor monolithic, single-file implementations that diverge sharply from human-written code.
Open the Receipts Pack → What each source proves, every figure traced, and what would change our verdict.