The trick: Narrowed Superlative
Mistral says Large 4 is the best open-weight model for coding.
On the one independent coding index it cites, its own post says it is effectively tied with GLM-5.3, at 48%.
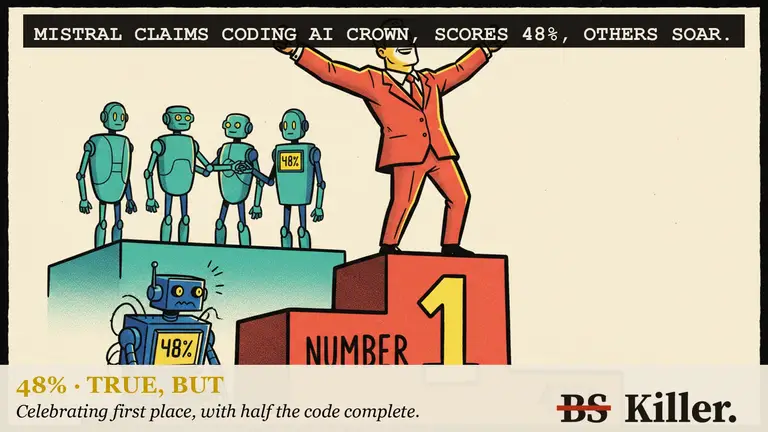
Mistral says Large 4 ranks as the best open-weight model for coding.
Before you read on. Your call?
TRUE, BUT
48%
Mistral's own post rests the lead on Terminal-Bench and Cognition's private FrontierCode 2.0, and calls its 48% on the Artificial Analysis Coding Agent Index effectively tied with GLM-5.3.
The twist
On the preview's broader intelligence index, Tom's Hardware reported at least five Chinese open models ahead.
There’s more to this story.
Membership opens the full investigation, the strongest counterargument and what to do with what you’ve learned.
30 days free, then A$89 a year. Payment card required. Cancel before the trial ends to avoid the first charge.
Review my 30-day free trial →- At sign-up: 30 days free. Payment card required. One introductory trial per customer.
- Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
- You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing hello@bskiller.com. This voluntary refund does not limit your rights under the Australian Consumer Law.
By starting your trial, you agree to the Terms.
Inferno Tech Pty Ltd t/a BS Killer, ABN 27 647 413 474
Get tomorrow’s check free by email.
Couldn't check your access. That's on us.
The trick has a name
We call it Narrowed Superlative: first or fastest, inside a quietly narrowed category. You'll see it again. Learn to spot it →
Receipts
- Supports mistral.ai:
Mistral Large 4 ranks as the best open-weight model for coding and among the world's most capable open models overall.
- Supports mistral.ai:
taking the lead on FrontierCode and Terminal-Bench while matching the best open-weight models on the Artificial Analysis Coding Agent Index
- Context mistral.ai:
On the Artificial Analysis Coding Agent Index, Mistral Large 4 scores 48%, effectively tied with the leading open-weight model, GLM-5.3, while using 47% fewer tokens per task on average.
- Context mistral.ai:
On Cognition's private FrontierCode 2.0 benchmark, which assesses end-to-end code quality and whether a repository maintainer would merge the agent's change, Mistral Large 4 leads with a score of 19.7%.
- Supports mistral.ai:
On Terminal-Bench 4.0, Mistral Large 4 improved by 13 percentage points to 41% compared to its public preview, taking the lead among open-weight models
- Context mistral.ai:
a full technical report is coming soon
- Refutes tomshardware.com:
At least five Chinese open models scored higher on the index
- Context tomshardware.com:
Its best result is a cyber test, but it falls behind on the index.
- Context datastudios.org:
Mistral reports 48% on the Artificial Analysis Coding Agent Index, which it calls effectively tied with Zhipu's GLM-5.3 while using 47% fewer tokens per task on average.
- Supports mistral.ai:
Just three weeks of additional reinforcement learning have since propelled it to the forefront of open-weight coding
Open the Receipts Pack → What each source proves, every figure traced, and what would change our verdict.