Start with two full samples. Sign in for this edition’s free story. Sources and corrections stay open.
What the pen marks mean
rememberThe takeaway: what to remember
figureThe number that matters
evidenceThe evidence line
rulingThe ruling
claimThe claim that fails
Each mark is drawn once, as you reach it. Numbers are only circled when they come from the story’s own figures.
01 / SafetyContestedFree sample
Accenture says the claims that a staffer's personal Claude agent ran on a Pentagon system were investigated and found without merit.
An Accenture spokesperson, statement to WIRED (29 October 2026) ·
AI illustration
Accenture told WIRED the allegations were thoroughly and independently investigated and found to be without merit.
The reality check
WIRED's sources say a staffer's personal Claude agent ran on a DOD system for two months and that Accenture did not first report it.
Why care? An unnamed investigation is not evidence, and neither are unnamed sources. If your staff use personal AI agents at work, this is the incident to check your own logs against.
Take this with youAccenture calls the claims about a staffer's Claude agent on a DOD system without merit, but would not tell WIRED who investigated or dispute an incident.
Open the evidence3 source pages +
The claim we checked
These allegations were thoroughly and independently investigated and found to be without merit.
These are quoted receipts, not a count of independent investigations. Several reports may rely on the same original source.
a contractor caused a security incident at the Department of Defense by connecting a secure centralized system used by multiple intelligence agencies to their personal account for Claude Code, Anthropic’s AI coding agent
When pressed, Accenture didn’t offer clarification on who conducted the investigation, or dispute that there had been what could be characterized as an incident.
Mistral says Large 4 is the best open-weight model for coding.
Mistral AI, release post for the Mistral Large 4 open weights (mistral.ai, 29 October 2026) ·
AI illustration
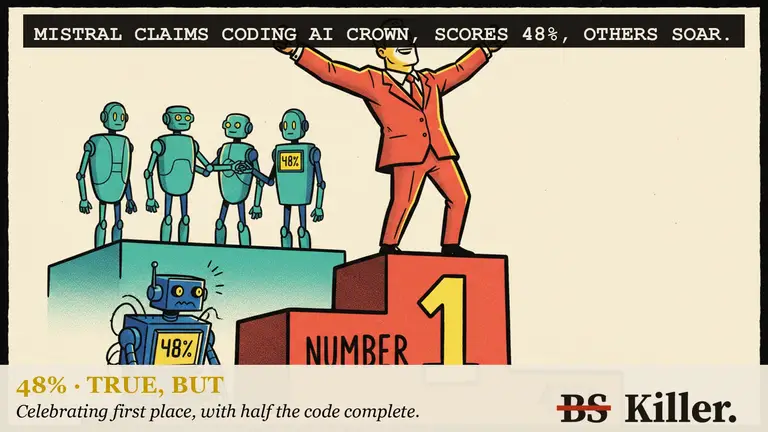
Mistral says Large 4 ranks as the best open-weight model for coding.
The reality check
Mistral's own post rests the lead on Terminal-Bench and Cognition's private FrontierCode 2.0, and calls its 48% on the Artificial Analysis Coding Agent Index effectively tied with GLM-5.3.
Why care? If you pick an open model for coding, the best label rests on two tests and a tie on the third. Run your own repository tasks against GLM-5.3 before switching.
Take this with youMistral leads two coding tests, one private, and its own post calls the independent Artificial Analysis coding score a tie with GLM-5.3.
Open the evidence3 source pages +
The claim we checked
Mistral Large 4 ranks as the best open-weight model for coding and among the world's most capable open models overall.
These are quoted receipts, not a count of independent investigations. Several reports may rely on the same original source.
On the Artificial Analysis Coding Agent Index, Mistral Large 4 scores 48%, effectively tied with the leading open-weight model, GLM-5.3, while using 47% fewer tokens per task on average.
On Cognition's private FrontierCode 2.0 benchmark, which assesses end-to-end code quality and whether a repository maintainer would merge the agent's change, Mistral Large 4 leads with a score of 19.7%.
On Terminal-Bench 4.0, Mistral Large 4 improved by 13 percentage points to 41% compared to its public preview, taking the lead among open-weight models
Mistral reports 48% on the Artificial Analysis Coding Agent Index, which it calls effectively tied with Zhipu's GLM-5.3 while using 47% fewer tokens per task on average.
In our experiments, an open-weight model reliably exploited the "patch gap" to compromise six recent Firefox releases, costing about $1,000 each to carry out
In all of our compromises of recent Firefox releases, GLM 5.3 also found and used an unpublished vulnerability in conjunction with those found via the patch gap.
Reading estimate: 418 words at 200 words per minute. Source quotes and the optional sections below add reading time.
Get tomorrow's check in your inbox.
One AI claim a night, checked against independent sources, receipts attached. Free.
At sign-up: 30 days free. Payment card required. One introductory trial per customer.
Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing hello@bskiller.com. This voluntary refund does not limit your rights under the Australian Consumer Law.