The trick: Lab Not Field
NVIDIA built a model that talks four times faster.
The work arrives 30 percent sooner.
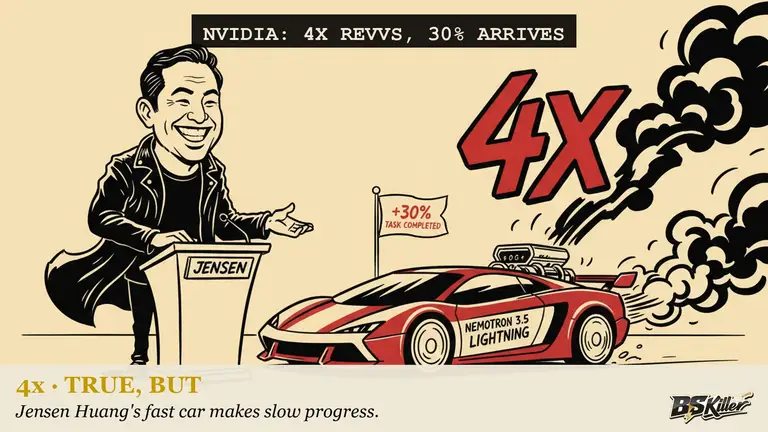
Nemotron 3.5 Lightning, NVIDIA's new 30B agent model with 3B active parameters, generates output up to 4x faster than similar-sized models and wins the accuracy-speed Pareto frontier.
Before you read on. Your call?
TRUE, BUT
4x
three sentences after the 4x, NVIDIA's own blog concedes that agent efficiency comes down to completed work, not token speed, and its own PinchBench chart shows tasks finishing 30% faster than Qwen3.6 35B. The 4x is 'up to', measured by the vendor, and Artificial Analysis's page for the model lists no output speed at all. A 4x engine revs; a 30% car arrives. Both numbers are NVIDIA grading NVIDIA.
There’s more to this story.
Membership opens the full investigation, the strongest counterargument and what to do with what you’ve learned.
30 days free, then A$89 a year. Payment card required. Cancel before the trial ends to avoid the first charge.
Review my 30-day free trial →- At sign-up: 30 days free. Payment card required. One introductory trial per customer.
- Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
- You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing hello@bskiller.com. This voluntary refund does not limit your rights under the Australian Consumer Law.
By starting your trial, you agree to the Terms.
BS Killer is published by Inferno Tech Pty Ltd, ABN 27 647 413 474.
Get tomorrow’s check free by email.
Couldn't check your access. That's on us.
The trick has a name
We call it Lab Not Field: it works in the test conditions, not the deployed ones. You'll see it again. Learn to spot it →
Receipts
- Supports developer.nvidia.com:
Nemotron 3.5 Lightning combines strong intelligence with up to 4x output speed of similar-sized models, placing it on the accuracy-speed Pareto frontier for high-volume agent workloads.
- Context developer.nvidia.com:
Agent efficiency ultimately comes down to how quickly a model completes useful work and not simply how fast it generates tokens. On PinchBench, Nemotron 3.5 Lightning reaches 86% accuracy while completing 10,000 tasks 30% faster than Qwen3.6 35B at similar accuracy.
- Refutes xenospectrum.com:
the "up to 4x" figure is NVIDIA's own claim, and Artificial Analysis's current model page does not list output speed. When deploying, completion times need to be re-measured using one's own prompt lengths and concurrency levels.
- Context datacamp.com:
NVIDIA claims it wins the accuracy-versus-speed Pareto frontier on the Artificial Analysis Intelligence Index, and reports up to 4x output speed of similar-sized models.
Open the Receipts Pack → What each source proves, every figure traced, and what would change our verdict.