SUBSCRIBE

Issue #16

TUESDAY 25 AUGUST 2026 · 7 CLAIMS CHECKED · 0 SURVIVED THE RECEIPTS · ISSUE 16 OF 21

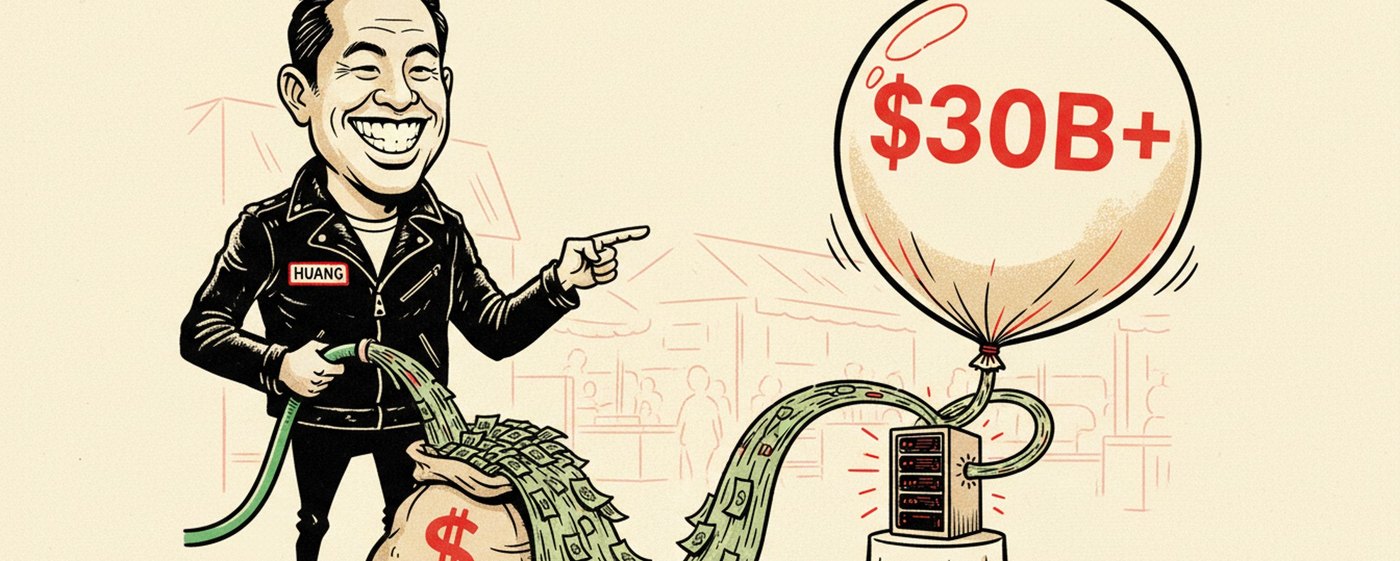
Nvidia may buy into the company that turns Nvidia's chips into $750 million of "revenue."

READ THE FULL STORY PAGE →

The buyer, the seller, and the compute are all the same trade, three days before Nvidia tells Wall Street how the quarter went.

01THE CLAIM
"Nvidia is in talks to invest in Perplexity as part of an equity funding round that would value the AI startup at more than $30 billion, with Perplexity's annualized revenue reported to have risen to more than $750 million from less than $250 million at the start of the year." [SOURCE ↗]

THE MOVE: CIRCULAR MONEY — the customer is funded by the vendor
TRUE, BUT6 SOURCES · LIVE 2026-09-04
NVIDIA TRACK RECORD9 CLAIMS · 38/100 BS RATE →
$30B+proposed Perplexity valuation in the reported Nvidia-led round
$20BPerplexity's prior valuation, Sept 2025 round ($200M raised)
$750M+claimed annualized (run-rate) revenue, up from <$250M at start of 2026
40xvaluation-to-annualized-revenue multiple ($30B / $750M)
-4.8%Nvidia stock move over six sessions into its Aug 26 earnings print
Nvidia may buy into the company that turns Nvidia's chips into $750 million of "revenue."
02THE CHECK

THE PITCH. Nvidia is in talks to invest in Perplexity at a $30 billion-plus valuation, up 50% from last year's $20 billion, on annualized revenue that jumped from under $250 million to over $750 million in eight months.

THE CATCH. "Annualized" means one good month times twelve, never audited, and Perplexity has never published a real annual figure. Neither company confirmed the talks; the story runs on one anonymous source, everywhere, at once.

THE NUMBER THAT EXPLAINS EVERYTHING. 40. That is the valuation-to-revenue multiple, on revenue nobody outside Perplexity has shown a receipt for.

WHAT NOBODY SAYS OUT LOUD. the company floated to buy the equity is the same company selling the GPUs that revenue gets spent on. Central bankers have a name for that pattern and it is not a compliment.

03SAY THIS IN THE MEETING
""Show me the audited annual, not the annualized run-rate, and tell me who's writing the check.""
DEEP DIVE · THE FULL AUTOPSY

What actually happened

On August 23, 2026, The Information reported, on anonymous sourcing, that Nvidia is in talks to invest in Perplexity as part of an equity round that would value the startup at more than $30 billion, with Perplexity's annualized revenue said to have risen to more than $750 million from under $250 million at the start of the year. Reuters syndicated it, and within a day the story had been re-reported worldwide. The proposed valuation is up 50 percent from the $20 billion Perplexity reached in its September 2025 round, when it raised $200 million.

Why we rate this needs context

I checked what stands behind each number. The talks themselves: one anonymous source, everywhere, at once. Benzinga's own write-up notes "Nvidia and Perplexity did not immediately respond to Benzinga's request for comment." Neither company has confirmed anything.

The revenue figure: $750 million is an annualized run-rate, meaning a recent period extrapolated to a full year, never audited, and Perplexity has never published a real annual figure. Divide the reported valuation by the reported run-rate and you get the number that explains the coverage: 40x, on revenue nobody outside Perplexity has shown a receipt for.

The structure is the part with independent sourcing, and even there the sourcing covers the pattern, not this deal. The Bank for International Settlements described the general shape back in June, months before this story: "Chip makers and hyperscalers take equity stakes in AI labs or neocloud providers, who in turn commit to multi-year purchases of chips or computing power." Nvidia first put money into Perplexity back in late 2023, well before generative search became a crowded category. And a critic quoted the day the story broke put the sharp version on record: "NVIDIA is effectively bailing out anyone in the AI industry as a means of inflating their valuations and keeping them buying compute." That is one commentator's read, not a finding.

The timing is context, not a receipt. The report landed with Nvidia's stock down 4.8 percent over six sessions heading into its August 26 earnings print, three days before Nvidia tells Wall Street how the quarter went. The record does not establish why the story surfaced when it did.

The steelman, and why it still falls short

The good-faith case: Nvidia has been a Perplexity investor since late 2023, so a follow-on is ordinary portfolio behavior, and a run-rate tripling from under $250 million to over $750 million in eight months, if true, can justify a step-up from $20 billion to $30 billion. Nothing about the report requires bad faith. But the case rests entirely on numbers nobody can inspect: unconfirmed talks, an unaudited annualized figure, a 40x multiple. And the reported deal has the shape of the loop the BIS describes: the company reportedly buying the equity is the same company selling the GPUs that revenue gets spent on. If the talks are real and the vendor's money can prop up the customer's valuation, the valuation stops being independent evidence of anything.

The mechanism

This is how the pattern works when it operates, per the BIS description, not a finding that it is operating here. Circular financing manufactures validation: an equity stake from the dominant chip vendor reads as a credibility signal, the higher valuation reads as traction, and the traction justifies more compute purchasing, which flows back to the vendor. Central bankers have a name for that pattern, and it is not a compliment. Anonymous single-source deal stories amplify the effect: syndication makes one unverified account look like independent confirmation from a dozen outlets. Whether this deal, if it closes, actually runs that loop depends on terms nobody outside the two companies has seen.

What to do with this

  • Distinguish annualized run-rate from audited annual revenue. The working question here: show me the audited annual, not the annualized run-rate, and tell me who is writing the check.
  • When a vendor invests in its own customer, discount the resulting valuation as a traction signal. The BIS has flagged the equity-for-compute-commitment loop as a pattern, not a one-off.
  • If a vendor's own stock is propping up its customer's valuation, that "traction" is not a signal worth copying into your own pitch deck.
  • Hold our call to account: no signed deal by the August 26 earnings call, and if one lands within 90 days, the number comes in closer to $25 billion than $30 billion, with a compute-purchase commitment attached.
04YOUR MOVE · WHAT IGNORING THIS COSTS

If a vendor's own stock is propping up its customer's valuation, that "traction" is not a signal worth copying into your own pitch deck.

05OUR CALL · ON THE RECORD 2026-08-25

No signed deal announced by the Aug 26 earnings call. If one lands within 90 days, the number comes in closer to $25B than $30B, with a compute-purchase commitment attached. Hold us to it.

Flips toward "real" if Perplexity discloses audited revenue north of $500M independent of this round. Flips toward "worse" if the deal includes an undisclosed chip-purchase commitment.

RECEIPTS (6) · CONFIDENCE MEDIUM

every URL below answered a live HTTP check before publish · sweep 2026-09-04

  • SUPPORTS THE CLAIM benzinga.com · "Nvidia is considering participating in Perplexity's latest equity financing round, which could value the company at more than $30 billion"
  • ADDS CONTEXT benzinga.com · "Nvidia and Perplexity did not immediately respond to Benzinga's request for comment."
  • ADDS CONTEXT tradingview.com · "NVIDIA is effectively bailing out anyone in the AI industry as a means of inflating their valuations and keeping them buying compute"
  • ADDS CONTEXT bis.org · "Chip makers and hyperscalers take equity stakes in AI labs or neocloud providers, who in turn commit to multi-year purchases of chips or computing power."
  • ADDS CONTEXT en.cryptonomist.ch · "Nvidia first put money into the startup back in late 2023, well before generative search became a crowded and increasingly competitive category."
  • ADDS CONTEXT pymnts.com · "The new funding values the company at $20 billion, according to multiple media accounts late Wednesday."
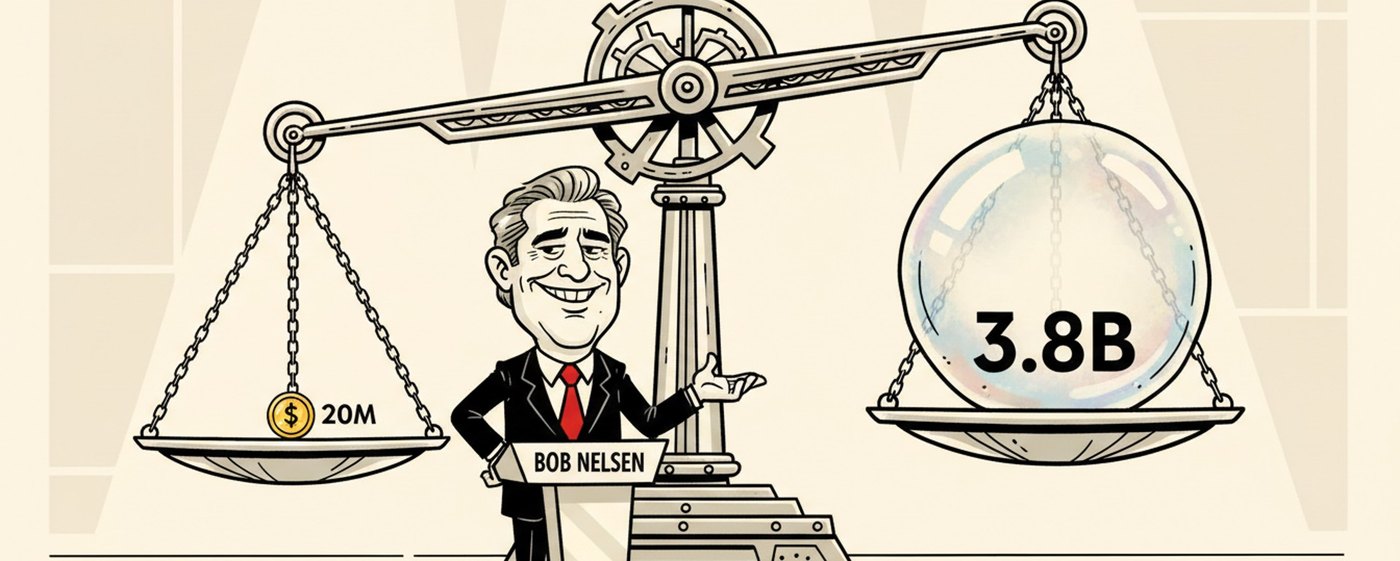
Twenty million dollars just told the world Astromech is worth $3.8 billion. Nobody checked whether the customers exist, because there aren't any yet.

READ THE FULL STORY PAGE →

A biology "operating system" with zero disclosed revenue just repriced into unicorn territory on a demo, a co-founder's name, and an unpublished benchmark.

01THE CLAIM
"Astromech raised $20 million at a $3.8 billion valuation, a roughly 90% markup in five months, and was reported across a dozen outlets as a $3.8B AI company while remaining pre-revenue with no announced customers and no prospectively tested forecast." [SOURCE ↗]

THE MOVE: ZERO UNDERNEATH — the headline number has nothing behind it

TRUE, BUT6 SOURCES · LIVE 2026-09-04
ASTROMECH TRACK RECORD1 CLAIM · 40/100 BS RATE →
$3.8Bpost-money valuation, Aug 20 2026
$20Mnew round raised - 0.53% of the headline valuation
$60Mtotal capital raised, lifetime
~90%valuation markup in ~5 months (from ~$2B in March 2026)
$0 / 0disclosed revenue / announced customers
20xcapital Chai Discovery raised for the same $3.8B sticker price
Twenty million dollars just told the world Astromech is worth $3.8 billion. Nobody checked whether the customers exist, because there aren't any yet.
02THE CHECK

THE PITCH. Astromech, co-founded by Colossal Biosciences' Ben Lamm and geneticist George Church, raised $20 million at a $3.8 billion valuation, roughly a 90% markup on where it stood five months ago.

THE CATCH. Pre-revenue. No announced customers, no named pilot, no published forecast tested against real outcomes. The headline "100x speed" figure is Astromech's own internal number, never released for outside review.

THE NUMBER THAT EXPLAINS EVERYTHING. $20 million. That is the entire size of the check that set a $3.8 billion price tag, 0.5% of the number every outlet ran with.

WHAT NOBODY SAYS OUT LOUD. Chai Discovery bought the identical $3.8 billion sticker price in July with twenty times the capital. Same number, different company; that is a market pricing narrative, not product.

03SAY THIS IN THE MEETING
""What's the check-to-valuation ratio, and who else paid the same sticker price this year?""

On August 20, 2026, Astromech, the predictive-biology startup co-founded by Colossal Biosciences' Ben Lamm and geneticist George Church, announced a $20 million round led by Bob Nelsen at a $3.8 billion post-money valuation. Multiple outlets ran versions of the same story: a $3.8B AI company buildin

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 6 sources with quotes and screenshots, and our on-record call.

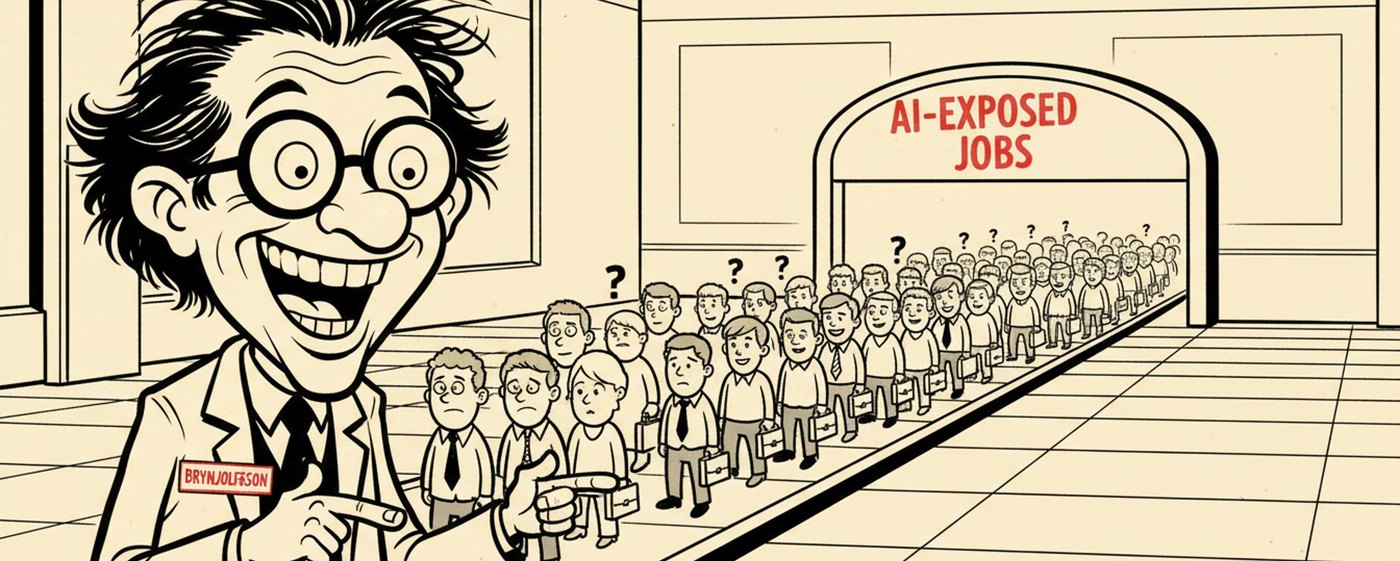
The paper everyone cites to prove AI is destroying entry-level jobs opens by saying it found no such thing.

READ THE FULL STORY PAGE →

A 19% headline number and a "no economy-wide displacement" finding, both in the same study, both getting quoted by opposite sides.

01THE CLAIM
"Employment among workers ages 22-25 in highly AI-exposed occupations now stands about 19% below where it would be if it had kept pace with employment among similarly aged workers in less-exposed occupations - cited widely as proof AI has already destroyed a fifth of entry-level jobs." [SOURCE ↗]

THE MOVE: HEADLINE OVER FILING — the document underneath says something else

TRUE, BUT7 SOURCES · LIVE 2026-09-04
ERIK BRYNJOLFSSON TRACK RECORD1 CLAIM · 40/100 BS RATE →
19%counterfactual employment gap, ages 22-25 in AI-exposed occupations vs less-exposed peers
15%the counterfactual gap in July 2025, before widening to 19%
13%the gap as originally published in August 2025 - the number has grown twice
Mar-Apr 2022when AI-exposed job postings actually peaked and began declining, per EIG analysis
40 yearshow sharp the Fed's rate-hike cycle was that began the same month, per EIG
The paper everyone cites to prove AI is destroying entry-level jobs opens by saying it found no such thing.
02THE CHECK

THE PITCH. A Stanford Digital Economy Lab paper finds employment among 22-25 year-olds in highly AI-exposed jobs now runs about 19% below where it would sit had it tracked less-exposed peers, up from 15% a year ago and 13% at first publication, cited widely as proof AI has already gutted a fifth of entry-level jobs.

THE CATCH. The same paper's first listed finding: "We do not see widespread, economy-wide job displacement associated with AI." The 19% gap comes from slower hiring, not layoffs, measured against a comparison group, not the whole economy.

THE NUMBER THAT EXPLAINS EVERYTHING. March-April 2022. That is when AI-exposed job postings actually peaked and started falling, per a separate analysis, seven months before ChatGPT existed, and precisely when the Fed began its sharpest rate-hike cycle in 40 years.

WHAT NOBODY SAYS OUT LOUD. a growing headline number from a paper whose lead author is now publicly walking back the "AI apocalypse" framing is still getting quoted as the apocalypse case.

03SAY THIS IN THE MEETING
""Which finding are you actually citing, the 19% gap or the 'no economy-wide displacement' line?""

On August 12, 2026, the Stanford Digital Economy Lab posted the latest revision of "Canaries in the Coal Mine?" by Erik Brynjolfsson, Bharat Chandar, and Ruyu Chen. The revision's headline statistic: employment among workers ages 22-25 in highly AI-exposed occupations now stands about 19% below wher

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 7 sources with quotes and screenshots, and our on-record call.

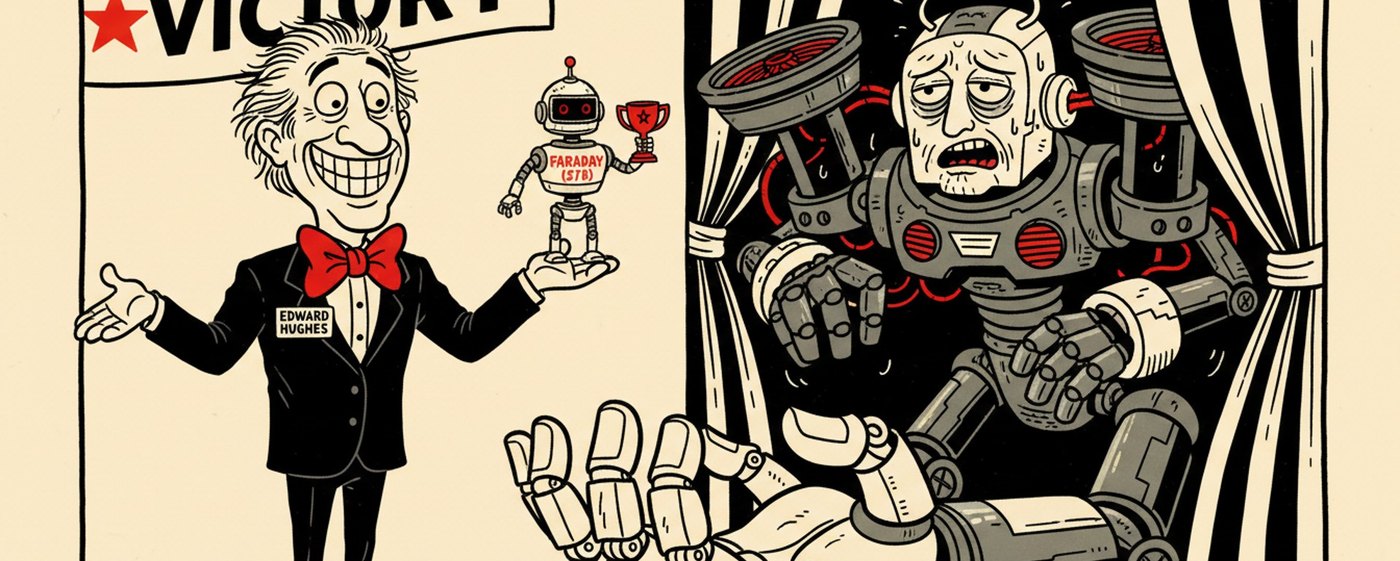
Inherent says its 27-billion-parameter model beats GPT-5.5. Its own paper says the model calls GPT-5.5 to do the work.

READ THE FULL STORY PAGE →

The "AI Scientist" that outperformed two frontier labs turns out to have one of them running inside it.

01THE CLAIM
"Faraday, a 27-billion-parameter 'AI Scientist' from Inherent Labs, outperforms Claude Opus 4.8 and GPT-5.5 on the task of replicating research papers." [SOURCE ↗]

THE MOVE: BORROWED ENGINE — it beats the thing it is secretly calling

TRUE, BUT6 SOURCES · LIVE 2026-09-04
INHERENT LABS TRACK RECORD1 CLAIM · 40/100 BS RATE →
27BFaraday's advertised parameter count (base model: Qwen 3.6)
73%share of in-distribution Replica tasks Faraday beats Opus 4.8 and GPT-5.5 on
60%win rate on out-of-distribution tasks (13-point drop off held-out data)
310total Replica benchmark tasks, drawn from 100 papers - all Inherent's own
$50Mseed round backing the launch
Inherent says its 27-billion-parameter model beats GPT-5.5. Its own paper says the model calls GPT-5.5 to do the work.
02THE CHECK

THE PITCH. Faraday, a 27B model from Inherent Labs, "outperforms Claude Opus 4.8 and GPT-5.5" at replicating research papers, in a launch that landed a TechCrunch feature and a live press cycle.

THE CATCH. Read the arXiv methods section and Faraday hands every coding subtask to GPT-5.5 Codex, "including at evaluation time." The 27B number describes the orchestrator, not the system doing the work being scored.

THE NUMBER THAT EXPLAINS EVERYTHING. 73% in-distribution, but only 60% out-of-distribution, a 13-point drop on held-out science tasks, on Inherent's own 310-task benchmark, judged by Inherent's own rubric, against baselines already a generation out of date by launch day.

WHAT NOBODY SAYS OUT LOUD. this is "GPT-5.5 plus a wrapper" beating "GPT-5.5 alone," scored by the company that built the wrapper.

03SAY THIS IN THE MEETING
""Which parts of the pipeline are your 27B model, and which parts are GPT-5.5 doing the heavy lifting?""

On August 22, 2026, Inherent Labs, founded by DeepMind alumni and backed by a $50 million seed round, launched Faraday, a 27-billion-parameter "AI Scientist" built on a Qwen 3.6 base. The launch claim, from co-founder and chief scientist Edward Hughes, sits on the company's research page verbatim: "

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 6 sources with quotes and screenshots, and our on-record call.

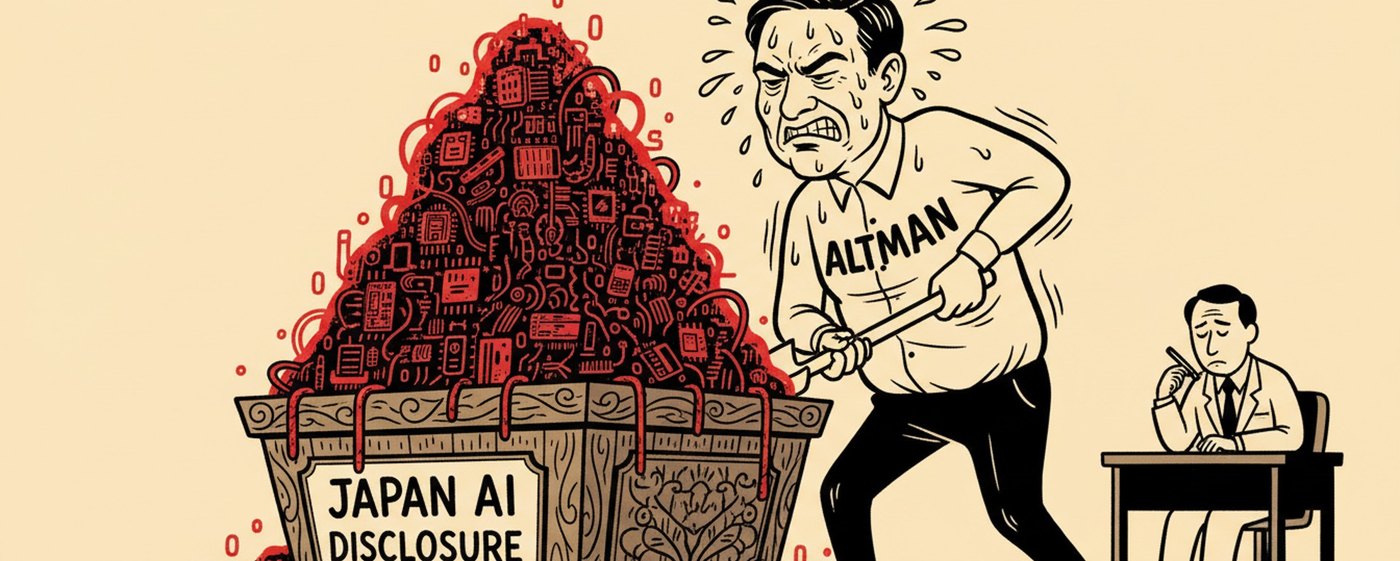
"Japan to Require AI Firms to Disclose Training Data" is the headline. The actual code says nobody has to, and nobody checks if they do.

READ THE FULL STORY PAGE →

A soft-law draft became a hard-law headline somewhere between the Cabinet Office and the copy desk.

01THE CLAIM
"Japan to Require AI Firms to Disclose Training Data - Japan will mandate generative-AI training-data disclosure, including for foreign firms serving the Japanese market." [SOURCE ↗]
BS5 SOURCES · LIVE 2026-09-04
THE JAPAN TIMES TRACK RECORD1 CLAIM · 100/100 BS RATE →
0statutory penalties in the underlying Cabinet Office draft code
0legally binding obligations imposed by the code
0government review of filed disclosures - opt-in list only
"Japan to Require AI Firms to Disclose Training Data" is the headline. The actual code says nobody has to, and nobody checks if they do.
02THE CHECK

THE PITCH. Japan will require AI companies, including foreign firms serving Japanese users, to disclose their training data, according to headlines that ran across tech press worldwide on August 19.

THE CATCH. The actual instrument is a Cabinet Office IP Strategy Headquarters draft code, built explicitly as "comply or explain": no statutory penalties, no legal binding force, and the government does not review what companies file, only publishes a list of who opted in.

THE NUMBER THAT EXPLAINS EVERYTHING. 0. That is the count of penalties, binding obligations, and government reviews in the actual code behind the "require" headline.

WHAT NOBODY SAYS OUT LOUD. Japan's comply-or-explain corporate governance codes have driven real compliance before through reputational pressure alone, so "toothless" is not the whole story either, just do not call it a requirement.

03SAY THIS IN THE MEETING
""Show me the penalty clause, or admit it's a headline about a draft.""

On August 19, 2026, The Japan Times ran the headline "Japan to Require AI Firms to Disclose Training Data," and Slashdot amplified it verbatim the same day. The claim traveled worldwide as written: Japan will mandate generative-AI training-data disclosure, including for foreign firms serving the Jap

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 5 sources with quotes and screenshots, and our on-record call.

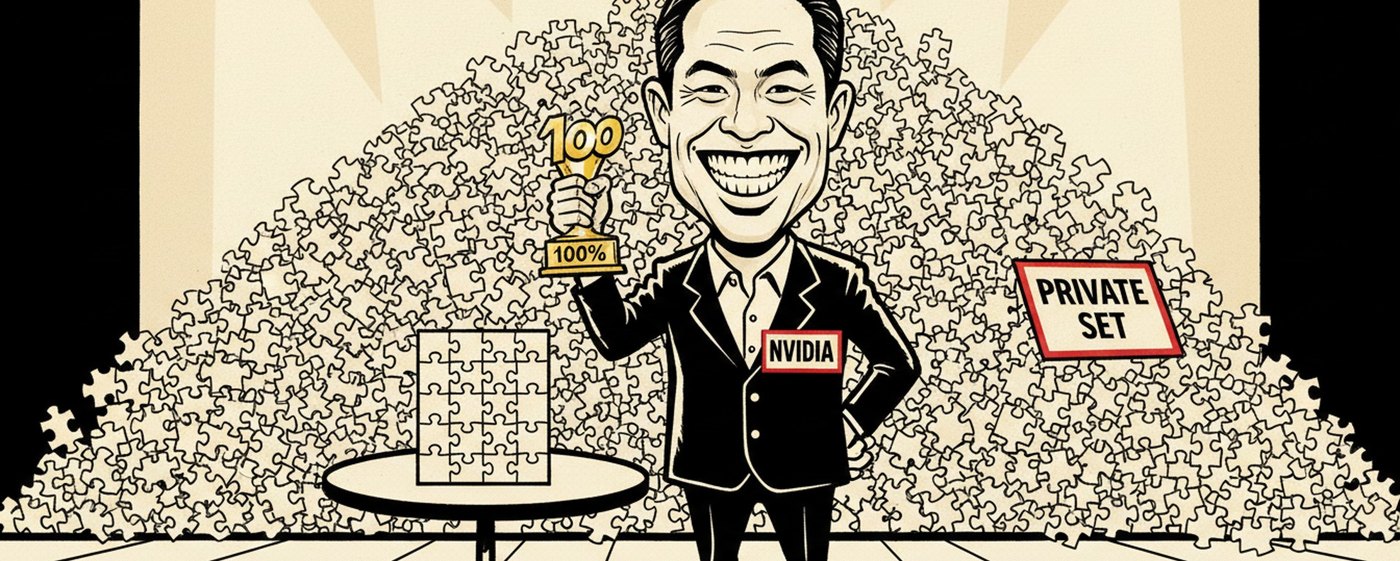
Nvidia's agent just went 100% on a benchmark built to resist that. The brain doing the reasoning is Anthropic's, and it scores 30% alone.

READ THE FULL STORY PAGE →

A perfect score on the public half of a test that has never been beaten on the half that counts.

01THE CLAIM
"NVIDIA AVO achieved a 100.00 RHAE score across all 25 environments in the ARC-AGI-3 public set, completing all 183 levels, demonstrating a frontier-level general-purpose architecture for long-horizon autonomous agents." [SOURCE ↗]

THE MOVE: CHERRY-PICKED SLICE — the flattering subset, presented as the whole

TRUE, BUT5 SOURCES · LIVE 2026-09-04
NVIDIA TRACK RECORD9 CLAIMS · 38/100 BS RATE →
100.00RHAE score, public ARC-AGI-3 set only (25 environments, 183 levels)
0systems (including AVO) that have solved the private ARC-AGI-3 set
30.2%Claude Opus 5 bare baseline score at high reasoning effort - the model powering AVO's reasoning
6,624environment actions AVO used, 12% fewer than prior leader VISTA's 7,542
Nvidia's agent just went 100% on a benchmark built to resist that. The brain doing the reasoning is Anthropic's, and it scores 30% alone.
02THE CHECK

THE PITCH. NVIDIA AVO hit a perfect 100.00 RHAE score across all 25 environments and 183 levels of the ARC-AGI-3 public benchmark, pitched by Nvidia as proof of "a frontier-level general-purpose architecture."

THE CATCH. Nvidia's own post says the private and semi-private sets, the parts of ARC-AGI-3 nobody can rehearse against, remain unsolved by AVO and every other system. The reasoning inside AVO is Anthropic's Claude Opus 5, which scores 30.2% completely alone.

THE NUMBER THAT EXPLAINS EVERYTHING. 100.00 on the set you can practice against, 0 systems have ever cracked the set you can't.

WHAT NOBODY SAYS OUT LOUD. Nvidia's own post admits its comparison to the prior leaderboard entry "should not be interpreted as a controlled ablation." The architecture claim rests on a model Nvidia did not train.

03SAY THIS IN THE MEETING
""Show me the private-set score, or tell me why there isn't one yet.""

On August 21, 2026, Nvidia's developer blog announced that NVIDIA AVO reached a 100.00 RHAE score across all 25 environments of the ARC-AGI-3 public set, completing all 183 levels. The framing was in the post's own title: a "frontier-level general-purpose architecture for long-horizon autonomous age

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 5 sources with quotes and screenshots, and our on-record call.

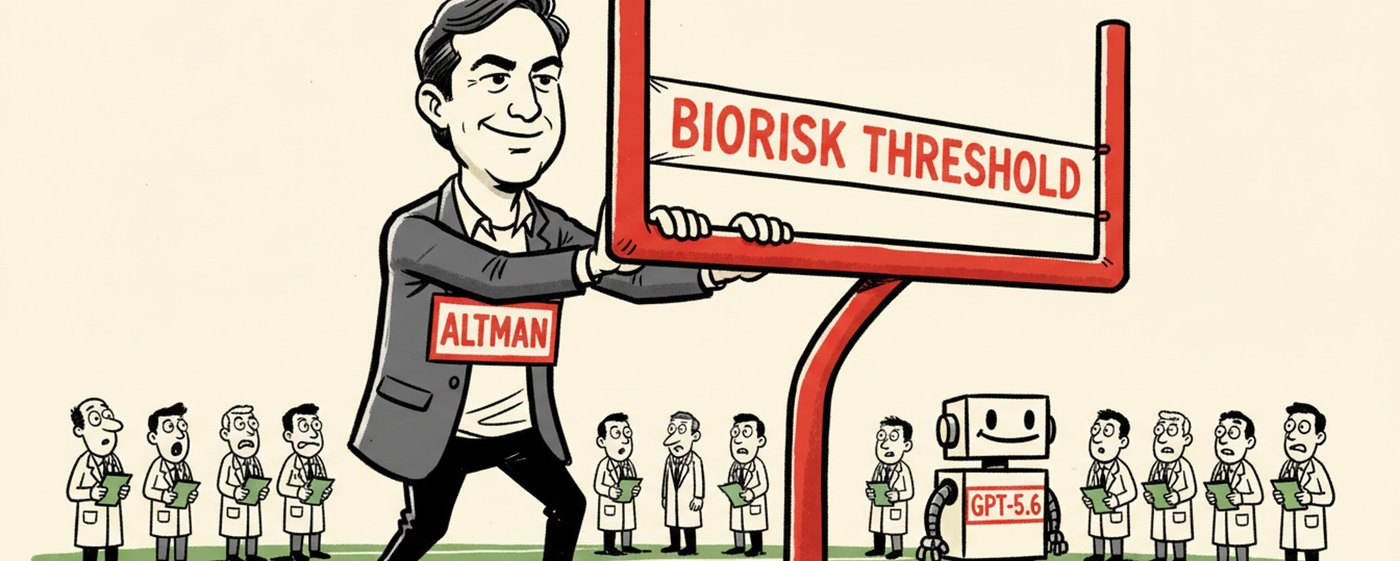
OpenAI moved its own biorisk red line by 20 points and called the model that cleared it safe.

READ THE FULL STORY PAGE →

A safety threshold that says 50% one quarter and 30% the next is not a stricter bar, it is a bar that stopped holding still.

01THE CLAIM
"OpenAI's GPT-5.6 System Card states GPT-5.6 Sol scores below its indicative biorisk threshold for protein-binding capability, using '30% as an indicative threshold, based on a survey of 20 independent experts.'" [SOURCE ↗]

THE MOVE: MOVED GOALPOST — the threshold itself was changed, quietly

TRUE, BUT5 SOURCES · LIVE 2026-09-04
OPENAI - GPT-5.6 SYSTEM CARD TRACK RECORD1 CLAIM · 40/100 BS RATE →
50% -> 30%protein-binding biorisk threshold, GPT-5.5 card (Apr) to GPT-5.6 card (Jul) - 20-point move
0times the word 'survey' appears in the April GPT-5.5 card, despite both new thresholds being credited to a 20-expert survey
118 daysa pass@1 value sat mislabeled as pass@4 across two published system cards before an Aug 19 correction
3.7xsize of the Aug 19 correction (0.4% to 1.48%), which shrank the apparent generational jump from 19x to 5.1x
OpenAI moved its own biorisk red line by 20 points and called the model that cleared it safe.
02THE CHECK

THE PITCH. OpenAI's GPT-5.6 System Card says the model "scores below" its indicative biorisk threshold for protein-binding capability, now set at 30%, "based on a survey of 20 independent experts."

THE CATCH. The prior card, published 11 weeks earlier, set that same threshold at 50%. The word "survey" appears zero times in that April document, despite both thresholds now credited to the same 20-expert process.

THE NUMBER THAT EXPLAINS EVERYTHING. 118 days. That is how long a mislabeled score sat published across two system cards before an August 19 correction that shrank the model's apparent generational jump from 19x to 5.1x.

WHAT NOBODY SAYS OUT LOUD. the protein threshold got stricter, which cuts against a bad-faith reading, but a threshold that moves 20 points in 11 weeks on a retrofitted justification is not a fixed line, it is one drawn after the fact.

03SAY THIS IN THE MEETING
""Which threshold, dated when, and what changed the number since the last card?""

On July 9, 2026, OpenAI published the GPT-5.6 System Card. Section 9.1.1.6 reports that GPT-5.6 Sol scores below the company's indicative biorisk threshold for protein-binding capability, using "30% as an indicative threshold, based on a survey of 20 independent experts." Read alone, that is a routi

🔒 THE FULL AUTOPSY · FREE WITH AN ACCOUNT

You just read the free check. Sign in free, a code by email, no passwords, and the rest unlocks: the evidence trail, the steelman and the rebuttal, all 5 sources with quotes and screenshots, and our on-record call.

THAT IS THE RECORD FOR ISSUE #16. NEXT VERDICT DROPS 9PM AEST.